Connecting to Iceberg
Apache Iceberg is a high-performance format for huge analytic tables. This document describes how to connect to Iceberg tables in PuppyGraph.
See also Tutorials for end-to-end tutorials for connecting to different Iceberg implementations.
Prerequisites
- Both the Iceberg Catalog and Storage are accessible over the network from the PuppyGraph instance.
- PuppyGraph supports various Iceberg implementations. Please see Metastore Configuration and Data Storage Configuration for supported implementations.
Configuration
The configuration consists of two parts: Metastore (Catalog) and Data Storage. Please configure them according to your Iceberg implementation. Optionally, tune the Metadata Cache.
Metastore Configuration
Iceberg REST
Iceberg REST Catalog defines a REST protocol allowing different Iceberg catalog implementations.
To use it, select Iceberg REST as the metastore type in the Web UI.
| Configuration | Explanation |
|---|---|
| RestUri | The server endpoint URI of the REST Catalog. |
| Warehouse | The name of the Iceberg warehouse. |
| Security | Security authentication mode of the REST catalog. |
| Credential | The Oauth2 client authentication credential. |
| Scope | Authorization scope for client credentials or token exchange |
The following sections provide specific configurations for different REST Catalog implementations.
Nessie
Project Nessie is a Transactional Catalog for Data Lakes with Git-like semantics. PuppyGraph supports Nessie through Iceberg REST Protocol.
PuppyGraph works with Nessie version 0.95.0 or higher. Please first configure Nessie Catalog with Iceberg REST before connecting.
After selecting Iceberg REST as the metastore type:
- Set
RestUrito the Nessie REST endpoint. Typically, this ends with/iceberglikehttp://127.0.0.1:19120/iceberg. - Set
Warehouseto the Nessie warehouse. This is typically the (base) storage location, for examples3://my-bucket/.
See also the following tutorials:
Polaris
Apache Polaris is an open-source, fully-featured catalog for Iceberg that implements Iceberg's REST API. PuppyGraph supports both Apache Polaris and Snowflake Open Catalog, a managed service for Polaris.
After selecting Iceberg REST as the metastore type:
- Set
RestUrito the Polaris REST endpoint. - Set
Warehouseto the Polaris warehouse accordingly. - Set
Scopeto the properPRINCIPAL_ROLEin Polaris. The format isPRINCIPAL_ROLE:<ROLE_NAME>. - Set
Credentialto the client auth credential if needed. The format is<CLIENT-ID>:<CLIENT-SECRET>.
See also the following tutorials for Polaris and Snowflake Open Catalog:
Snowflake Horizon
Snowflake Horizon Catalog exposes the Snowflake-managed Iceberg tables of a Snowflake account through an Iceberg REST endpoint. PuppyGraph reads the table metadata from Horizon Catalog and reads the data files directly from storage, using credentials that Snowflake vends for each table.
In the Web UI, select Snowflake Horizon (Iceberg REST) as the metastore type. This is a preset of Iceberg REST: PuppyGraph saves the catalog as an Iceberg REST catalog ("type": "rest") with Iceberg view support disabled.
| Field | Value |
|---|---|
| REST Endpoint URL | https://<org>-<account>.snowflakecomputing.com/polaris/api/catalog. Replace underscores in the organization or account name with hyphens. |
| REST Warehouse | The name of the Snowflake database that contains the Iceberg tables. Use upper case if the database was created without quotes. |
| REST Authentication Type | OAuth 2.0 Client Credentials. |
| OAuth 2.0 Credential | A Snowflake programmatic access token (PAT). |
| OAuth 2.0 Scope | session:role:<role>, where <role> is the PAT's role restriction. The role needs USAGE on the database and schema and SELECT on the Iceberg tables. |
| OAuth 2.0 Server URI | https://<org>-<account>.snowflakecomputing.com/polaris/api/catalog/v1/oauth/tokens. |
| Iceberg view support | Disabled — skip Iceberg views on this catalog. The preset selects it. Keep it selected. |
| Storage type | Get from metastore, so PuppyGraph uses the storage credentials vended by Horizon Catalog. |
Iceberg view support must be disabled ("restCatalogViewEndpointsMode": "off" in a schema file). Horizon Catalog advertises the Iceberg view endpoints but rejects view requests with HTTP 403, which fails the whole table listing rather than only the views. With view support disabled, PuppyGraph does not request views, so Iceberg views in Horizon Catalog are not available.
Catalogs created from a schema file or the API
A catalog in a schema file has no Horizon preset. Set "type": "rest" and "restCatalogViewEndpointsMode": "off" explicitly, and omit the storage section to get vended credentials. See Snowflake Horizon + vended credentials for a complete example.
This setup is for Snowflake-managed Iceberg tables. It does not cover Snowflake's preview of Horizon Catalog access to externally managed Iceberg tables in catalog-linked databases. Snowflake native tables are not in Horizon Catalog. Use Connecting to Snowflake for them.
Use a PAT as the OAuth 2.0 Credential. By default, Snowflake lets a service user create or use a PAT only when a network policy applies to the user, and Horizon Catalog does not support network policies set at the user level. Before you create the PAT, attach an authentication policy to the service user that removes this requirement:
CREATE AUTHENTICATION POLICY <policy_name>
  PAT_POLICY = (NETWORK_POLICY_EVALUATION = ENFORCED_NOT_REQUIRED);
ALTER USER <service_user> SET AUTHENTICATION POLICY <policy_name>;
Alternatively, your Snowflake administrator can activate an account-level network policy that allows the PuppyGraph host's egress IP addresses. See Create a programmatic access token in the tutorial for the full setup.
Do not use a key-pair JWT as the credential for a lasting connection. Horizon Catalog accepts one, but it expires one hour after it is created by default, and PuppyGraph does not create a new one.
See also the following tutorial:
Tabular
Tabular is a cloud-native managed storage engine that provides a range of services on top of Apache Iceberg tables.
After selecting Iceberg REST as the metastore type:
- Set
RestUrito the Tabular REST endpoint. It is https://api.tabular.io/ws by default. - Set
Warehouseto the name of the Tabular warehouse - Set
Credentialto the Tabular member or service credential.
Google Cloud Lakehouse
Google Cloud Lakehouse (formerly BigLake) is a storage engine that unifies data warehouses and lakes. PuppyGraph supports Google Cloud Lakehouse through its Iceberg REST Catalog API.
PuppyGraph uses Application Default Credentials (ADC) for authentication. See Authentication for PuppyGraph to access Google Cloud resources for how to configure credentials.
In the Web UI, after selecting Google BigLake REST as the metastore type:
- Set
Endpoint URLto the REST catalog URI, which is generallyhttps://biglake.googleapis.com/iceberg/v1/restcatalog. - Set
Warehouseto the GCS bucket path. The format isgs://BUCKET_NAME. - Set
GCP User Projectto your Google Cloud project ID. - Set
Storage typeasGet from metastore.
See also the following tutorial:
AWS Glue
| Configuration | Explanation |
|---|---|
| Region | The region of the AWS Glue Data Catalog. Example: us-east-1. See AWS Glue endpoints and quotas for more details. |
| Use instance profile | Whether to use role-based authentication (Explicit IAM roles or instance-profile attached) |
| IAM Role ARN | The ARN of the IAM role for accessing the AWS Glue Data Catalog. Required by authentication with IAM roles. |
| Access key | The access key of the IAM user for accessing the AWS Glue Data Catalog. Required by authentication with IAM User Access keys. |
| Secret key | The secret key of the IAM user for accessing the AWS Glue Data Catalog. Required by authentication with IAM User Access keys. |
Amazon S3 Tables
Amazon S3 Tables provide S3 storage that’s optimized for analytics workloads, with features designed to continuously improve query performance and reduce storage costs for tables.
To connect to the data from PuppyGraph, you need a user account with proper permissions (at least AmazonS3TablesReadOnlyAccess).
| Configuration | Explanation |
|---|---|
| useDefaultCredentialsProviderChain | Whether to use Default Authentication. Default value false. See Using Default Authentication in PuppyGraph for more details. |
| Region | The region of the AWS S3 Table Bucket. Example: us-east-1. See S3 Tables AWS Regions, endpoints, and service quotas for more details. |
| Access key | The access key of the IAM user for accessing the Amazon S3 Tables. Required by authentication with IAM User Access keys. |
| Secret key | The secret key of the IAM user for accessing the Amazon S3 Tables. Required by authentication with IAM User Access keys. |
| Warehouse | The table bucket ARN of the Amazon S3 table bucket. |
Hive Metastore
| Configuration | Explanation |
|---|---|
| Hive metastore URI | The URI of your Hive metastore. Format: thrift://<metastore_IP_address>:<metastore_port>. |
OneLake Table APIs for Iceberg
OneLake offers a REST API endpoint for interacting with tables in Microsoft Fabric. This endpoint can be used with clients and libraries that are compatible with the Iceberg REST Catalog (IRC) API open standard or the Unity Catalog API open standard.
You need to gather the following information before connecting PuppyGraph to OneLake Table APIs for Iceberg:
| Placeholder | Description |
|---|---|
<fabric_workspace_id> |
The ID of your Microsoft Fabric workspace |
<fabric_data_item_id> |
The ID of the lakehouse data item |
<client_id> |
The client ID of the service principal |
<client_secret> |
The client secret of the service principal |
<tenant_id> |
Your Microsoft Entra ID tenant ID - see endpoint |
After selecting Iceberg REST as the metastore type:
-
Set
Endpoint URLashttps://onelake.table.fabric.microsoft.com/iceberg. -
Set
Warehouseas<fabric_workspace_id>/<fabric_data_item_id>. -
Set
Credentialto the OAuth2 client authentication credential. The format is<client_id>:<client_secret>. Optionally, setClient IDandClient Secretdirectly. -
Set
Scopetohttps://storage.azure.com/.default. -
Set
Rest oauth2 server uritohttps://login.microsoftonline.com/<tenant_id>/oauth2/v2.0/token.
Data Storage Configuration
Get from metastore
There is no need to specify Storage configuration with the following implementation of Iceberg:
- HDFS with Hive Metastore
- Iceberg REST Catalog with credential vending.
Select Get from metastore in the Web UI for these implementations.
Vended credentials do not include a storage endpoint. If the catalog vends credentials for Amazon S3 but the bucket is reachable only through a private endpoint (for example AWS PrivateLink), select Amazon S3 instead of Get from metastore, set S3 Authentication Type to Credentials vended by the catalog, and set Region and Endpoint for the private endpoint. PuppyGraph then uses the vended credentials with that endpoint.
Amazon S3 (Simple Storage Service)
PuppyGraph supports Amazon S3 (Simple Storage Service) for Iceberg.
| Configuration | Explanation |
|---|---|
| Region | The region of the Amazon S3. Example: us-east-1. See Amazon Simple Storage Service endpoints and quotas for more details. |
| Use instance profile | Whether to use role-based authentication (Explicit IAM roles or instance-profile attached). |
| IAM Role ARN | The ARN of the IAM role for accessing the Amazon S3. Required by authentication with IAM roles. |
| Access key | The access key of the IAM user for accessing the Amazon S3. Required by authentication with IAM User Access keys. |
| Secret key | The secret key of the IAM user for accessing the Amazon S3. Required by authentication with IAM User Access keys. |
Amazon S3 Compatible Storage
PuppyGraph supports S3 Compatible Storage (e.g. RustFS or MinIO AIStor) for Iceberg.
| Configuration | Explanation |
|---|---|
| Endpoint | The S3 compatible storage endpoint. |
| Access key | The access key of an IAM user for accessing the S3 compatible storage. |
| Secret key | The secret key of an IAM user for accessing the S3 compatible storage. |
| Enable SSL | Whether to enable SSL connection for accessing the S3 compatible storage. |
| Enable path style access | Whether to use path-style access method when accessing the S3 compatible storage. |
GCS (Google Cloud Storage)
PuppyGraph supports GCS (Google Cloud Storage) for Iceberg.
Using VM instance
| Configuration | Explanation |
|---|---|
| useComputeEngineServiceAccount | Use Compute Engine service account, set to true here |
Using VM instance impersonate a service account
| Configuration | Explanation |
|---|---|
| useComputeEngineServiceAccount | Use Compute Engine service account, set to true here |
| impersonationServiceAccount | Impersonation service account |
Using service account
| Configuration | Explanation |
|---|---|
| serviceAccountEmail | Service account email address associated with your Google Cloud project |
| serviceAccountPrivateKeyId | Unique identifier for the service account's private key |
| serviceAccountPrivateKey | Service account's private key for authentication |
Using service account impersonate another service account
| Configuration | Explanation |
|---|---|
| serviceAccountEmail | Service account email address associated with your Google Cloud project |
| serviceAccountPrivateKeyId | Unique identifier for the service account's private key |
| serviceAccountPrivateKey | Service account's private key for authentication |
| impersonationServiceAccount | Impersonation service account |
Azure Onelake Storage
PuppyGraph supports Azure OneLake Storage for Iceberg.
| Configuration | Explanation |
|---|---|
| Client ID | The Application (client) ID of the Azure AD app registered for authentication. |
| Client Secret | The client secret (password) generated in the Azure AD app registration. Used together with the client ID for authentication. |
| Client Endpoint | The OAuth2 token endpoint of your Azure Active Directory tenant. |
Metadata Cache
PuppyGraph caches Iceberg metadata so that a query does not have to ask the catalog and read metadata files from storage every time it plans. The cached metadata includes each table's current version (its snapshot and schema), partitions, and the lists of data and delete files. Because a cached table version can be older than the one in the catalog, these settings also bound how stale query results can be.
The cache is on by default, and the defaults suit most deployments. In the Web UI, the settings are in the catalog form under Advanced configuration. In a schema file, they are in a metadataCache object at the top level of the catalog entry, next to metastore and storage. Every field is optional, and an omitted field keeps its default.
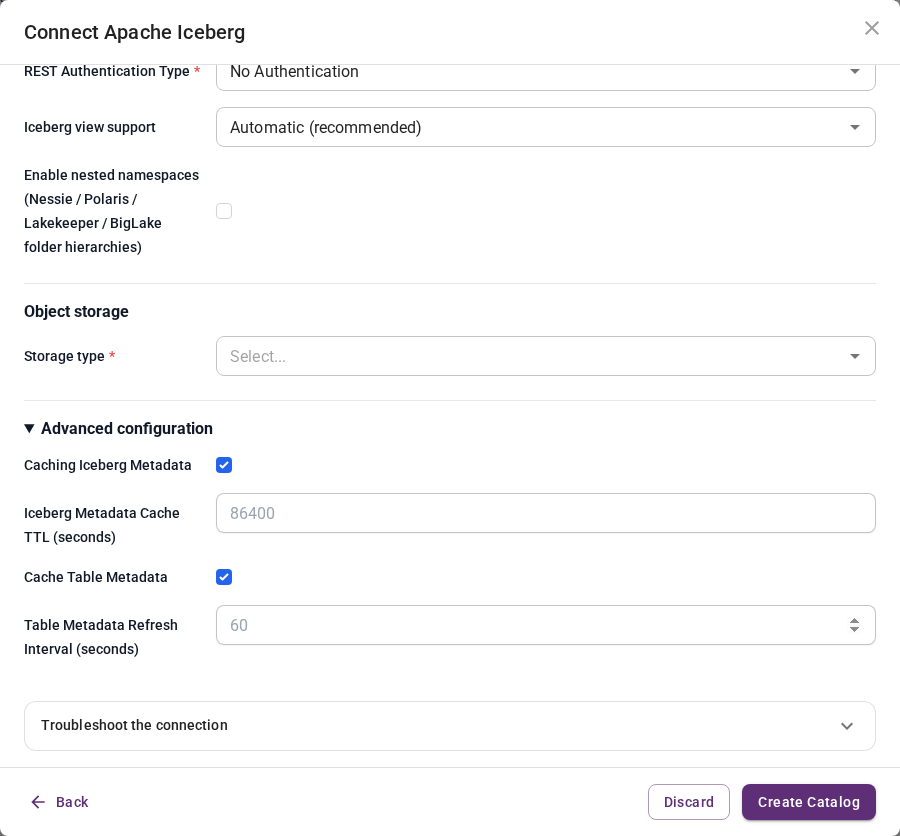
| Web UI label | Schema key | Default | Explanation |
|---|---|---|---|
| Caching Iceberg Metadata | metadataCache.enabled |
true |
Whether to cache Iceberg metadata at all. Set to false to turn off every cache below, including the table metadata cache. Every query then loads metadata from the catalog and storage, which slows query planning and adds load on the catalog. |
| Iceberg Metadata Cache TTL (seconds) | metadataCache.ttlSeconds |
86400 (24 hours) |
How long a cached entry is kept. One TTL applies to every metadata cache in the catalog: table versions, partitions, and data and delete file lists. For an Iceberg REST catalog, cached table versions are kept for at most 3000 seconds even when the TTL is longer. |
| Cache Table Metadata | metadataCache.tableMetadata.enabled |
true |
Whether to cache table versions. Set to false to load the table version from the catalog for every query while still caching partitions and file lists. |
| Table Metadata Refresh Interval (seconds) | metadataCache.tableMetadata.refreshIntervalSeconds |
60 |
The minimum time between two reloads of a table version, so that a frequently queried table is not reloaded from the catalog on every query. It is not a schedule: a query reloads a cached table version only when the version was loaded at least this long ago, and nothing is reloaded while the table is not queried. 0 turns off these query-triggered reloads, so a cached table version is reloaded only after the TTL expires or by background refresh. |
| Not in the Web UI | metadataCache.dataFileManifest.memoryUsageRatio |
0.1 |
The largest fraction of the leader's JVM heap that the data file list cache may use. |
How stale a table version can be
By default, a table version is reloaded only when a query reads it, never on a timer. When a query reads a table whose cached version was loaded more than the refresh interval ago, PuppyGraph reloads the table from the catalog in the background, and that query still runs on the cached version. Queries after the reload completes use the new version. The refresh interval only limits how often these reloads happen and does not trigger any by itself. A table that is queried continuously therefore lags the catalog by about one refresh interval. A table that has not been queried for a while serves its first query on the version from its last load, which can be much older than the refresh interval. To keep table versions current without waiting for a query, turn on background refresh.
The TTL is the upper bound. It counts from the last time the table version was loaded successfully, and querying the table does not extend it. If refreshes keep failing, for example because the catalog is unreachable, PuppyGraph stops using the cached version once the TTL expires (or sooner with background refresh on), and queries on that table fail until the catalog is reachable again. With the defaults, a cached table version is therefore at most 24 hours old, or at most 3000 seconds old for an Iceberg REST catalog.
To bound staleness more tightly, lower ttlSeconds, for example to 3600. A shorter TTL means more metadata loads from the catalog and storage, but only for tables that are actually queried.
Background refresh
Version requirement
DATALAKE_METADATA_BACKGROUND_REFRESH_ENABLED and DATALAKE_METADATA_BACKGROUND_REFRESH_INTERVAL are available in PuppyGraph 1.15.0 and later.
With background refresh on, each leader reloads cached table versions from the catalog on a schedule, independently of queries. A table that has been idle since a commit can then pick up the new version before the next query reads it. This is not read-after-write consistency: a query that arrives before the leader serving it has completed a refresh pass since the commit still runs on the older cached version. Background refresh is off by default.
The table metadata refresh interval does not keep table versions fresh. It is the minimum time between two reloads of a table version, so that frequent queries do not overload the catalog, and it never triggers a reload by itself. Background refresh is what keeps them fresh: it reloads every recently read table on a schedule, so its interval, not the refresh interval, bounds how far such a table lags the catalog.
Turn it on with these environment variables. For a single-container deployment, pass them to docker run with -e. For a cluster, set them on the leaders, for example under env.leader in the Helm chart values. For a single-node Helm install, set them under env.singleNode, because env.leader is not used in that mode.
| Environment variable | Default | Explanation |
|---|---|---|
DATALAKE_METADATA_BACKGROUND_REFRESH_ENABLED |
false |
Set to true to turn on background refresh. |
DATALAKE_METADATA_BACKGROUND_REFRESH_INTERVAL |
10m |
The pause between two background refresh passes, as a duration such as 2m or 30s. It must be between 1ms and 596h31m23.647s, otherwise PuppyGraph fails to start. |
The leaders read these variables only at startup, so changing them requires restarting the leaders.
In each pass, a leader goes through the cached table versions of every Iceberg catalog, one table at a time (any Hive or Paimon catalogs you have connected are refreshed in the same pass):
- A table that a query has read in the last 24 hours is reloaded from the catalog. If the table has a new version, it replaces the cached one, and the partitions of the new version and its newly added data file lists are loaded into the cache as well. Queries keep running on the cached version during the reload and do not wait for it.
- A table that no query has read in the last 24 hours is removed from the cache. The next query on it loads it from the catalog.
- If reloading a table fails, the table is removed from the cache, so the next query on it loads it from the catalog. While the catalog is unreachable, queries on that table therefore fail from the next pass on, instead of running on the cached version until the TTL expires.
A table that has been read in the last 24 hours therefore lags the catalog by at most one interval plus the time a pass takes. The refresh interval and TTL above still apply, except that a failed reload no longer keeps the cached version until the TTL expires.
Background refresh only reloads table versions that are in the cache, so it has no effect when Caching Iceberg Metadata or Cache Table Metadata is off.
Each pass loads every recently read table from the catalog, on every leader. A short interval on a deployment that reads many tables therefore multiplies the requests to the catalog.
Example
In the following catalog entry, a query reloads a table version only if it has been cached for at least 30 seconds, and cached metadata is kept for at most one hour:
{
  "catalog": [
    {
      "name": "iceberg_rest_s3",
      "type": "iceberg",
      "metastore": {
        "type": "rest",
        "uri": "http://127.0.0.1:8181"
      },
      "metadataCache": {
        "enabled": "true",
        "ttlSeconds": "3600",
        "tableMetadata": {
          "enabled": "true",
          "refreshIntervalSeconds": "30"
        }
      },
      "storage": {
        "useInstanceProfile": "false",
        "region": "us-west-2",
        "accessKey": "AKIAIOSFODNN7EXAMPLE",
        "secretKey": "wJalrXUtnFEMI/K7MDENG/bPxRfiCYEXAMPLEKEY",
        "enableSsl": "true"
      }
    }
  ]
}
Changing the cache settings of an existing catalog
To change these settings on a catalog that already exists, edit its metadataCache object in the schema and upload the schema with catalog changes allowed: tick Allow changes to existing catalogs in the upload dialog, or add allowCatalogUpdate=true to the REST request. See How an upload is applied.
The change applies to the running catalog without a restart, on every leader. Applying it empties the catalog's metadata cache on every leader, so the next queries on each table load fresh metadata from the catalog. Uploading the same values again changes nothing and keeps the cache.
Tutorials
- Querying Google Cloud Lakehouse Iceberg Tables Data as a Graph
- Querying Iceberg Data as a Graph
- Querying Nessie Data as a Graph
- Querying Azure OneLake Data as a Graph
- Querying Snowflake Open Catalog Data as a Graph
- Querying Snowflake Horizon Iceberg Data as a Graph
- Querying Polaris Data as a Graph
- Querying Amazon S3 Tables Data as a Graph
- Run Graph Queries on Apache Iceberg Tables with Dremio & Puppygraph
Data Type Mapping
| Iceberg Type | PuppyGraph Type | Description |
|---|---|---|
boolean |
Boolean |
True or false |
int |
Int |
32-bit signed integers |
long |
Long |
64-bit signed integers |
float |
Float |
32-bit IEEE 754 floating point |
double |
Double |
64-bit IEEE 754 floating point |
decimal(P, S) |
Decimal(P, S) |
Fixed-point decimal; precision P, scale S |
string |
String |
Arbitrary-length character sequences |
date |
Date |
Calendar date without timezone or time |
time |
Time |
Time of day, microsecond precision, without date, timezone |
timestamp |
DateTime |
Timestamp, microsecond precision, without timezone |
list |
Array<E> |
A collection of values with some element type |
struct |
Struct<field1 E1[,field2 E2...]> |
A tuple of typed values |
If you need a data type that is not supported, or one that is not listed here, contact us.
Example Configurations
| Catalog Type | Storage Type | Example Configuration |
|---|---|---|
| REST Catalog | Amazon S3 | #rest-catalog-amazon-s3 |
| REST Catalog | RustFS | #rest-catalog-rustfs |
| REST Catalog | OneLake | #rest-catalog-azure-onelake |
| Snowflake Horizon | Vended credentials | #snowflake-horizon-vended-credentials |
| AWS Glue | Amazon S3 | #aws-glue-amazon-s3 |
| Hive Metastore | HDFS | #hive-metastore-hdfs |
| Hive Metastore | Amazon S3 | #hive-metastore-amazon-s3 |
| Hive Metastore | RustFS | #hive-metastore-rustfs |
| Hive Metastore | Google GCS | #hive-metastore-google-gcs |
| Hive Metastore | Azure Blob | #hive-metastore-azure-blob |
| Hive Metastore | Azure Data Lake Gen2 | #hive-metastore-azure-data-lake-gen2 |
REST Catalog + Amazon S3
{
  "catalog": [
    {
      "name": "iceberg_rest_s3",
      "type": "iceberg",
      "metastore": {
        "type": "rest",
        "uri": "http://127.0.0.1:8181"
      },
      "storage": {
        "useInstanceProfile": "false",
        "region": "us-west-2",
        "accessKey": "AKIAIOSFODNN7EXAMPLE",
        "secretKey": "wJalrXUtnFEMI/K7MDENG/bPxRfiCYEXAMPLEKEY",
        "enableSsl": "false"
      }
    }
  ]
}
REST Catalog + RustFS
{
  "catalog": [
    {
      "name": "iceberg_rest_rustfs",
      "type": "iceberg",
      "metastore": {
        "type": "rest",
        "uri": "http://127.0.0.1:8181"
      },
      "storage": {
        "useInstanceProfile": "false",
        "accessKey": "admin",
        "secretKey": "password",
        "enableSsl": "false",
        "endpoint": "http://127.0.0.1:9000",
        "enablePathStyleAccess": "true"
      }
    }
  ]
}
REST Catalog + Azure OneLake
{
  "catalog": [
      {
        "name": "az_iceberg",
        "type": "iceberg",
        "metastore": {
          "type": "rest",
          "uri": "http://127.0.0.1:8181"
        },
        "storage": {
          "type": "AzureDLS2",
          "clientId": "<oauth-2.0-client-id>",
          "clientSecret": "<oauth-2.0-client-secret>",
          "clientEndpoint": "<oauth-2.0-token-endpoint>"
        }
      }
    ]
}
Snowflake Horizon + vended credentials
{
  "catalog": [
    {
      "name": "horizon_data",
      "type": "iceberg",
      "metastore": {
        "type": "rest",
        "uri": "https://<org>-<account>.snowflakecomputing.com/polaris/api/catalog",
        "warehouse": "<SNOWFLAKE_DATABASE>",
        "authType": "oauth2",
        "security": "oauth2",
        "credential": "<programmatic_access_token>",
        "scope": "session:role:<ROLE>",
        "oauthServerUri": "https://<org>-<account>.snowflakecomputing.com/polaris/api/catalog/v1/oauth/tokens",
        "restCatalogViewEndpointsMode": "off"
      }
    }
  ]
}
AWS Glue + Amazon S3
{
  "catalog": [
    {
      "name": "iceberg_glue_s3",
      "type": "iceberg",
      "metastore": {
        "type": "glue",
        "useInstanceProfile": "false",
        "region": "us-west-2",
        "accessKey": "AKIAIOSFODNN7EXAMPLE",
        "secretKey": "wJalrXUtnFEMI/K7MDENG/bPxRfiCYEXAMPLEKEY"
      },
      "storage": {
        "useInstanceProfile": "false",
        "region": "us-west-2",
        "accessKey": "AKIAIOSFODNN7EXAMPLE",
        "secretKey": "wJalrXUtnFEMI/K7MDENG/bPxRfiCYEXAMPLEKEY",
        "enableSsl": "false"
      }
    }
  ]
}
Amazon S3 Tables + Amazon S3
{
  "catalog": [
        {
          "name": "iceberg_s3tables_s3",
          "type": "iceberg",
          "metastore": {
            "type": "s3tables",
            "region": "us-west-2",
            "accessKey": "AKIAIOSFODNN7EXAMPLE",
            "secretKey": "wJalrXUtnFEMI/K7MDENG/bPxRfiCYEXAMPLEKEY",
            "warehouse": "arn:aws:s3tables:us-west-2:111122223333:bucket/bucket-name123",
            "useDefaultCredentialsProviderChain": "false"
          },
          "storage": {
            "useDefaultCredentialsProviderChain": "false",
            "useInstanceProfile": "false",
            "region": "us-west-2",
            "accessKey": "AKIAIOSFODNN7EXAMPLE",
            "secretKey": "wJalrXUtnFEMI/K7MDENG/bPxRfiCYEXAMPLEKEY",
            "enableSsl": "true",
            "type": "S3"
          }
        }
      ]
}
Amazon S3 Tables + Amazon S3 using Default Authentication
{
  "catalog": [
        {
          "name": "iceberg_s3tables_s3",
          "type": "iceberg",
          "metastore": {
            "type": "s3tables",
            "region": "us-west-2",
            "useDefaultCredentialsProviderChain": "true",
            "useInstanceProfile": "false",
            "warehouse": "arn:aws:s3tables:us-west-2:111122223333:bucket/bucket-name123"
          },
          "storage": {
            "useDefaultCredentialsProviderChain": "true",
            "useInstanceProfile": "false",
            "region": "us-west-2",
            "type": "S3"
          }
        }
      ]
}
Hive Metastore + HDFS
{
  "catalog": [
    {
      "name": "iceberg_hms_hdfs",
      "type": "iceberg",
      "metastore": {
        "type": "HMS",
        "hiveMetastoreUrl": "thrift://127.0.0.1:9083"
      }
    }
  ]
}
Hive Metastore + RustFS
{
  "catalog": [
    {
      "name": "iceberg_hms_rustfs",
      "type": "iceberg",
      "metastore": {
        "type": "HMS",
        "hiveMetastoreUrl": "thrift://127.0.0.1:9083"
      },
      "storage": {
        "useInstanceProfile": "false",
        "accessKey": "admin",
        "secretKey": "password",
        "enableSsl": "false",
        "endpoint": "http://127.0.0.1:9000",
        "enablePathStyleAccess": "true"
      }
    }
  ]
}
Hive Metastore + Amazon S3
{
  "catalog": [
    {
      "name": "iceberg_hms_s3",
      "type": "iceberg",
      "metastore": {
        "type": "HMS",
        "hiveMetastoreUrl": "thrift://127.0.0.1:9083"
      },
      "storage": {
        "useInstanceProfile": "false",
        "region": "us-west-2",
        "accessKey": "AKIAIOSFODNN7EXAMPLE",
        "secretKey": "wJalrXUtnFEMI/K7MDENG/bPxRfiCYEXAMPLEKEY",
        "enableSsl": "false"
      }
    }
  ]
}
Hive Metastore + Google GCS
{
  "catalog": [
    {
      "name": "iceberg_hms_gcs",
      "type": "iceberg",
      "metastore": {
        "type": "HMS",
        "hiveMetastoreUrl": "thrift://127.0.0.1:9083"
      },
      "storage": {
        "type": "GCS",
        "serviceAccountEmail": "acc_name@project.iam.gserviceaccount.com",
        "serviceAccountPrivateKeyId": "AKIAIOSFODNN7EXAMPLE",
        "serviceAccountPrivateKey": "-----BEGIN PRIVATE KEY-----\nabcded\n-----END PRIVATE KEY-----\n"
      }
    }
  ]
}
Hive Metastore + Azure Blob
{
  "catalog": [
    {
      "name": "iceberg_hms_azblob",
      "type": "iceberg",
      "metastore": {
        "type": "HMS",
        "hiveMetastoreUrl": "thrift://127.0.0.1:9083"
      },
      "storage": {
        "type": "AzureBlob",
        "storageAccount": "account_name",
        "storageContainer": "container_name",
        "sasToken": "sp=rl&st=2020-12-15T03:19:48Z&se=2024-12-12T11:19:48Z&sv=2022-11-02&sr=c&sig=1"
      }
    }
  ]
}
Hive Metastore + Azure Data Lake Gen2
{
  "catalog": [
    {
      "name": "iceberg_hms_azgen2",
      "type": "iceberg",
      "metastore": {
        "type": "HMS",
        "hiveMetastoreUrl": "thrift://127.0.0.1:9083"
      },
      "storage": {
        "type": "AzureDLS2",
        "clientId": "000000-avaf-aaaa-bbbb-aba988azfa",
        "clientSecret": "EXAMPLEvonefPJabcde",
        "clientEndpoint": "https://login.microsoftonline.com/000000-avaf-aaaa-bbbb-aba988azfa/oauth2/token"
      }
    }
  ]
}
To change, delete, or troubleshoot this catalog after you save it, see Managing catalogs.